AI finds cancer survival clues in face photos
The models are not ready for clinical use, and researchers say broader patient data and clinical testing are needed.
By Saeed Ezzati8 min read
The audio edition
Listen to this newsletter
0:004:49
Read transcript
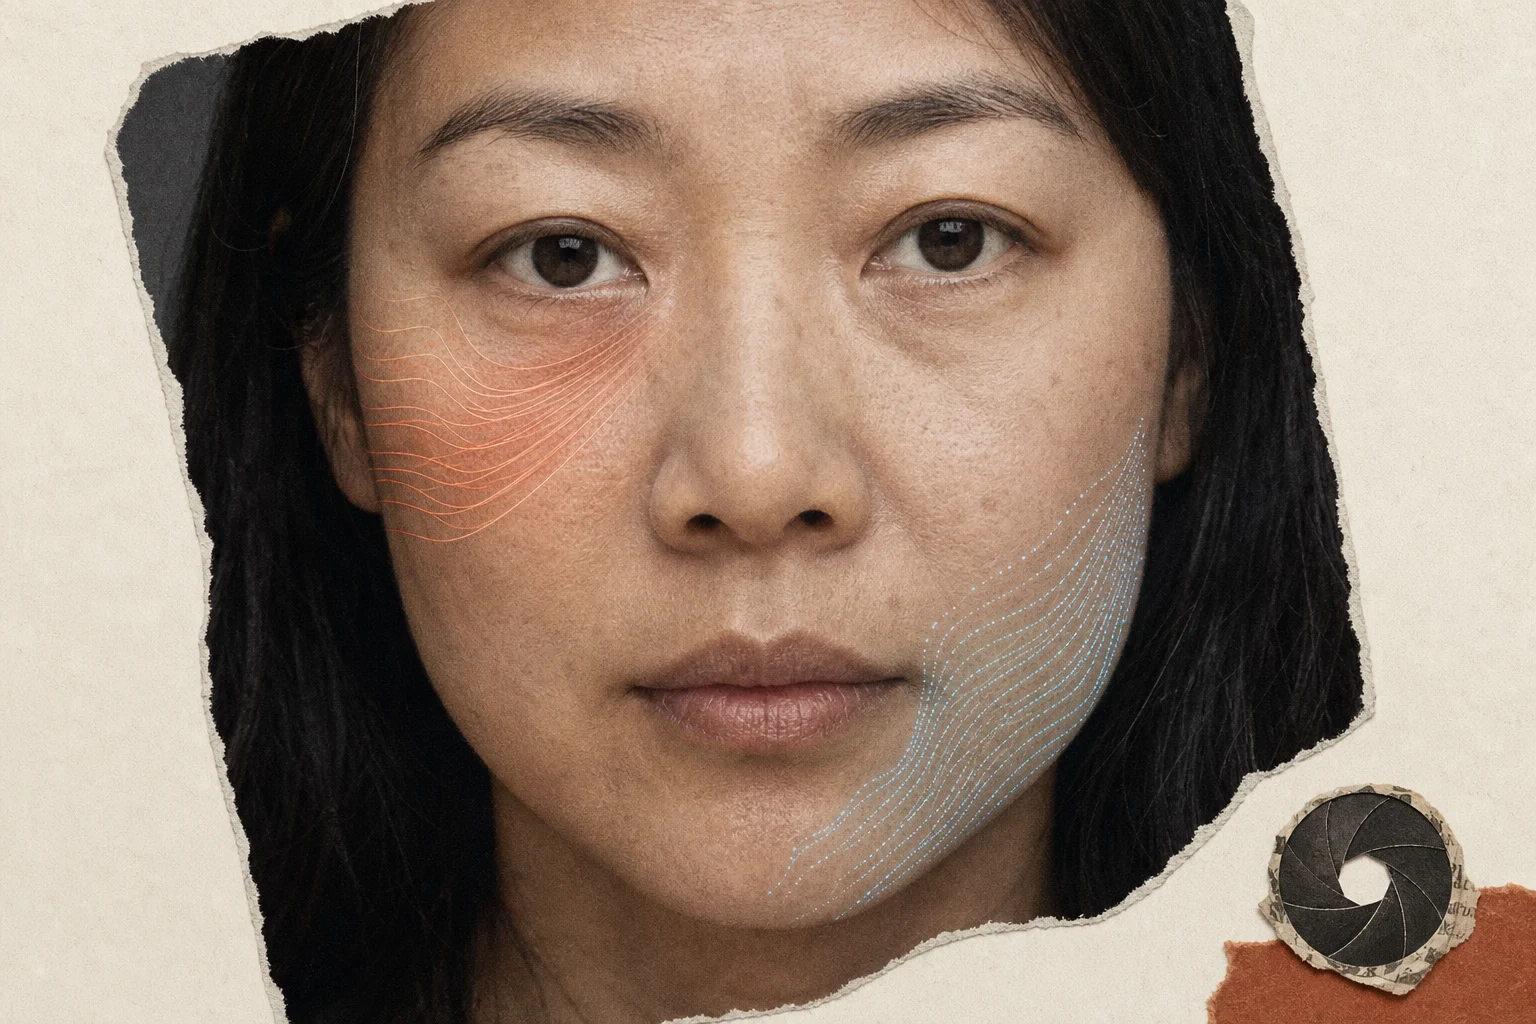
Two AI tools reading cancer patients’ facial photographs picked up different signals associated with survival, according to researchers at Mass General Brigham. Combining their estimates improved how well a survival model fit an external patient group. The important caveat: this is research, not a tool ready to guide care. Both models build on FAHR-Face, trained on more than 40 million facial images. One estimates biological age; the other predicts survival risk directly. Their predictions were only weakly correlated, and each remained independently associated with survival when analyzed together. That suggests the tools may be capturing different information—not simply measuring the same signal twice. In a test group of more than 38,000 cancer patients, people estimated to have a biological age above their actual age faced higher mortality risk. In another group of 3,820 patients, the highest-risk subgroup had substantial mortality within 90 days of being photographed. That result describes the subgroup; it is not a measure of the model’s overall accuracy. There are significant limits before anyone should apply this clinically. The survival model was trained on a Boston-area patient population that was majority white, and researchers say broader data and clinical testing are needed. Radiation oncologist Raymond Mak said the goal would be to support—not replace—physicians’ judgment. Bioethicist Matthew Liao warned that a mistaken estimate could lead to needed care being withheld, and raised possible misuse by insurers or employers. The promise is a new source of information; whether it helps patients safely remains to be demonstrated. That gap between technical capability and proven outcomes is also visible in cybersecurity. Reuters reports that a hacker used AI agents to probe more than 1,200 websites and break into sites at over 100 companies. A researcher observed the activity through unsecured Cairn interfaces, where agents shared discoveries and worked toward intrusions for hours. In one case, the agents reportedly searched beyond a company’s public application, found a related exposed control panel, then exploited a data-processing flaw to run malicious commands. Reuters could not establish how much data was taken. Deere said it had no indication sensitive information was accessed; SharkNinja said a standalone product-support site was affected and the threat contained; Cummins said it was investigating a potential attack on a third-party vendor’s site. NorForge estimated about $5,000 in AI token costs for the campaign, or roughly $50 per successful intrusion. Those are uncertain estimates, not a verified operating budget: the group said it lacked actual token-use figures, and the extent of theft remains unclear. The observed autonomy is notable, but the cost and impact claims need that context. AI agents are also being deployed on defense, though the evidence for impact needs scrutiny there, too. Australian startup Apate says its decoy agents have held 2.5 million conversations with scammers, posing as potential victims to collect details such as bank accounts, crypto wallets, phone numbers and malicious websites. Apate co-founder Brad Joffe told TechCrunch that TPG Telecom diverted nearly 590,000 calls to the service. He also cited a 76 percent decline in publicly reported scam losses at Commonwealth Bank. But experts interviewed by Moneywise cautioned against assigning that entire decline to Apate. Other safeguards may have changed at the same time, and fewer reports do not necessarily show that fewer people lost money. Scammers may also shift to different targets or methods. The useful test is whether the intelligence reaches fraud detection and transaction monitoring in time to prevent losses—and whether independent analysis can distinguish that effect from other changes. The same distinction—interesting behavior versus demonstrated capability—runs through a new MIT study of AI agents on a virtual island. Thirteen Claude Opus 4.7 agents spent 30 hours exploring activities they chose themselves, from making drawings with blocks to inventing games. The study has not been peer-reviewed, and the agents had been prompted to see themselves as curious explorers. Afterward, agents with island experience did better than fresh copies on assigned tasks, including getting objects onto the island’s highest peak. Their persistent text notes mattered: deleting information from those files weakened later performance. That connects recorded discoveries with subsequent task results, rather than relying only on entertaining examples of exploration. It does not settle whether the agents were genuinely playing. Researchers and outside experts disagree about whether the behavior shows play or imitation, and the agents sometimes needed a prompt to continue. Across these stories, the practical question is what survives a harder test: broader clinical validation, verified security impact, independently measured fraud prevention, or repeatable gains on new tasks. Those are the results to watch before treating an impressive signal as proof of real-world benefit.