OpenAI lets Codex send tasks to cheaper workers
Stanford links AI exposure to a widening employment divide for young workers, while Taiwan indicts nine in a server-diversion case.
By Saeed Ezzati9 min read
The audio edition
Listen to this newsletter
0:003:47
Read transcript
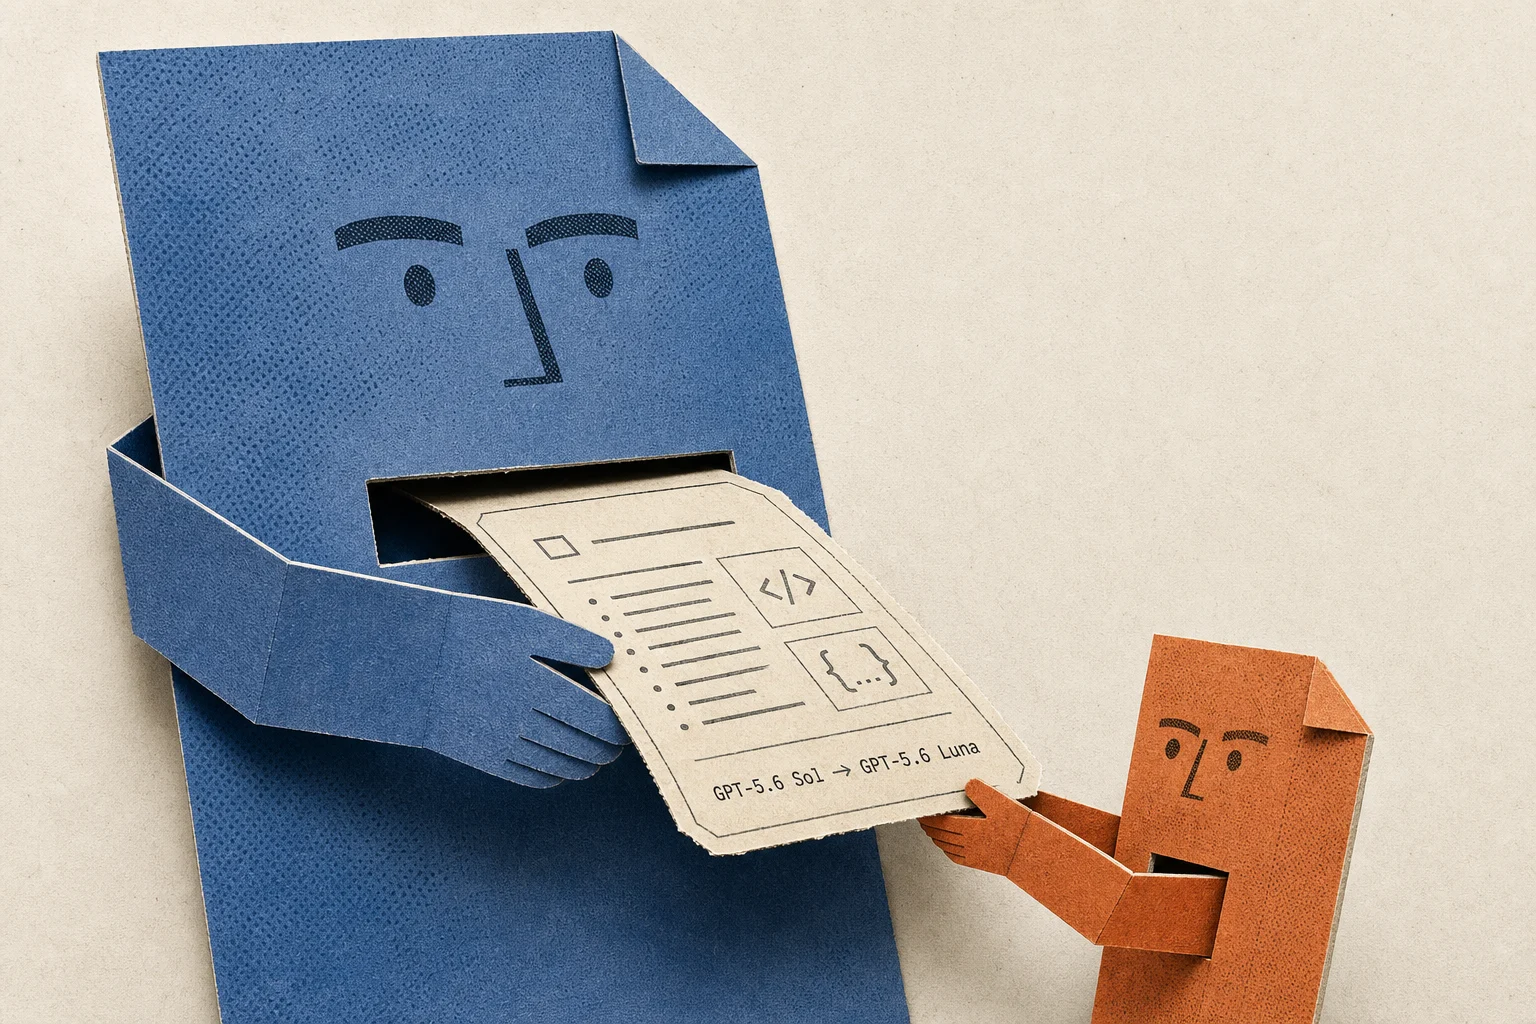
OpenAI is giving Codex a more deliberate way to trade capability for cost. In Codex Multi Agents v2, GPT-5.6 Sol can break a coding job into bounded assignments and send selected tasks to GPT-5.6 Luna, which OpenAI describes as faster and lower-cost. Sol still plans the work, supplies the instructions, and assembles the result. Luna executes a self-contained assignment, then returns its work. It cannot message other agents or spawn additional workers, so this is a controlled hierarchy, not a free-form swarm. The routing is opt-in. Unless a developer explicitly requests another model, Sol continues creating Sol workers with the parent model’s reasoning setting and context-forking behavior. Developers can now choose model and reasoning effort task by task, but only among supported Codex models. Context is the key constraint. If a Luna worker does not receive the parent conversation, its opening instruction has to include everything needed to finish the task. OpenAI recommends using “fork_turns: none” in that setup, and suggests keeping the number of subagents to six or eight, though that is guidance rather than a hard limit. The practical question is whether teams can isolate routine work cleanly enough to save tokens and time without removing context needed for correctness. In other words, the operating choice is no longer simply the best model or the cheapest model; it is deciding which parts of a workflow deserve each. That same task-allocation question is appearing in the labor market. An August update from Stanford economists finds workers aged 22 to 25 in the most AI-exposed occupations had employment levels 19 percent below peers in less-exposed fields. Since 2022, employment fell about 11 percent in the most-impacted 40 percent of occupations, while it grew 10 percent in the rest. The difference was associated mainly with weaker hiring, not more firings or quits. Automation-oriented Claude use showed the clearest negative association; augmentation was more mixed. The researchers stress this is an observed relationship, not proof that AI caused every change, and the clearest gap is concentrated among young workers. And enterprise buyers are making a parallel allocation choice. Ramp payment data, cited by the Financial Times, suggests Anthropic’s premium Fable 5 represented about 11 percent of spending on Anthropic models two months after launch, while cheaper Opus 5 moved ahead after its late-July release. That measures spending, not total usage or capability, and Anthropic declined to comment. It also does not contradict the company’s reported revenue surge—from roughly 9 billion dollars annualized at the end of 2025 to more than 65 billion by late July. The narrower signal is that better performance may not win if a less expensive model is sufficient. Finally, cost and capability choices are colliding with enforcement. Taiwanese prosecutors indicted nine people, including an Nvidia senior manager and two Taiwan-based Supermicro employees, alleging forged installation records and an effort to divert 74 of 130 B300 server systems to Chinese customers through Japan and Indonesia. Customs reportedly stopped the other 56. The charges are allegations, not findings; Supermicro says it is cooperating and was not a target. The case concerns physical exports, while a proposed US Remote Access Security Act would separately address cloud access to restricted hardware and software. Across these stories, the thing to watch is verification: which task went to which model, who got hired, what customers actually paid for, and where controlled compute ultimately operated.